interpretable_pool() returns 42 pre-configured generator instances,
built from 15 of SynForecast’s 32 generator classes with one class per
behavioral niche. The niches span ARMA and exponential smoothing,
long-range memory, volatility clustering, intermittent demand,
deterministic chaos, counts, and bounded and heavy-tailed processes.
It is the default corpus behind
generate_series, and a bias-free
starting point for benchmarking or pretraining: generators are allocated
proportionally to each niche’s behavioral range, so no single domain
dominates the pool. The list is ordered round-robin across the niches,
so any prefix spans as many distinct behaviors as possible: a
generate_series panel smaller than the pool still gets one niche per
series.
What’s in, and what’s deliberately out The pool draws from interpretable, single-mechanism generators — each slot is one named data-generating process. The meta-generators (TSIGenerator,TCMGenerator,KernelSynthGenerator,MARGenerator) are excluded on purpose: they already randomize across many behaviors internally, so folding them in would blur the one-niche-one-mechanism design. Use thepretraining_pool()preset for maximal breadth in foundation-model pretraining; it bundles those meta-generators, withinterpretable_poolincluded by default.
Which pool?
interpretable_poolwhen every series should be one named, interpretable process: benchmarking a method against known mechanisms, stress-testing a pipeline, or building a panel whose behaviours you can name. It is the default behindgenerate_series.pretraining_poolwhen breadth matters more than interpretability, as in pretraining a foundation model. It contains the whole interpretable pool plus randomised meta-generators;include_interpretable=Falsegives a purely procedural corpus.seasonal_pool, added on top of either, when the target data has a strong regular yearly cycle on a moving level: tourism, hospital, or retail demand at quarterly or monthly frequency.pretraining_pool(include_seasonal=True)appends it for you. Add it, never substitute it for part of a pool, and skip it for intermittent or weakly seasonal data. The feature-space coverage page shows where it helps and where it does not.
Generate an interpretable dataset
Create 42 generators and generate one series per generator.Generator names
Each generator has a descriptive name indicating its type and configuration.Overview: all 42 series
A compact grid showing every series in the interpretable pool.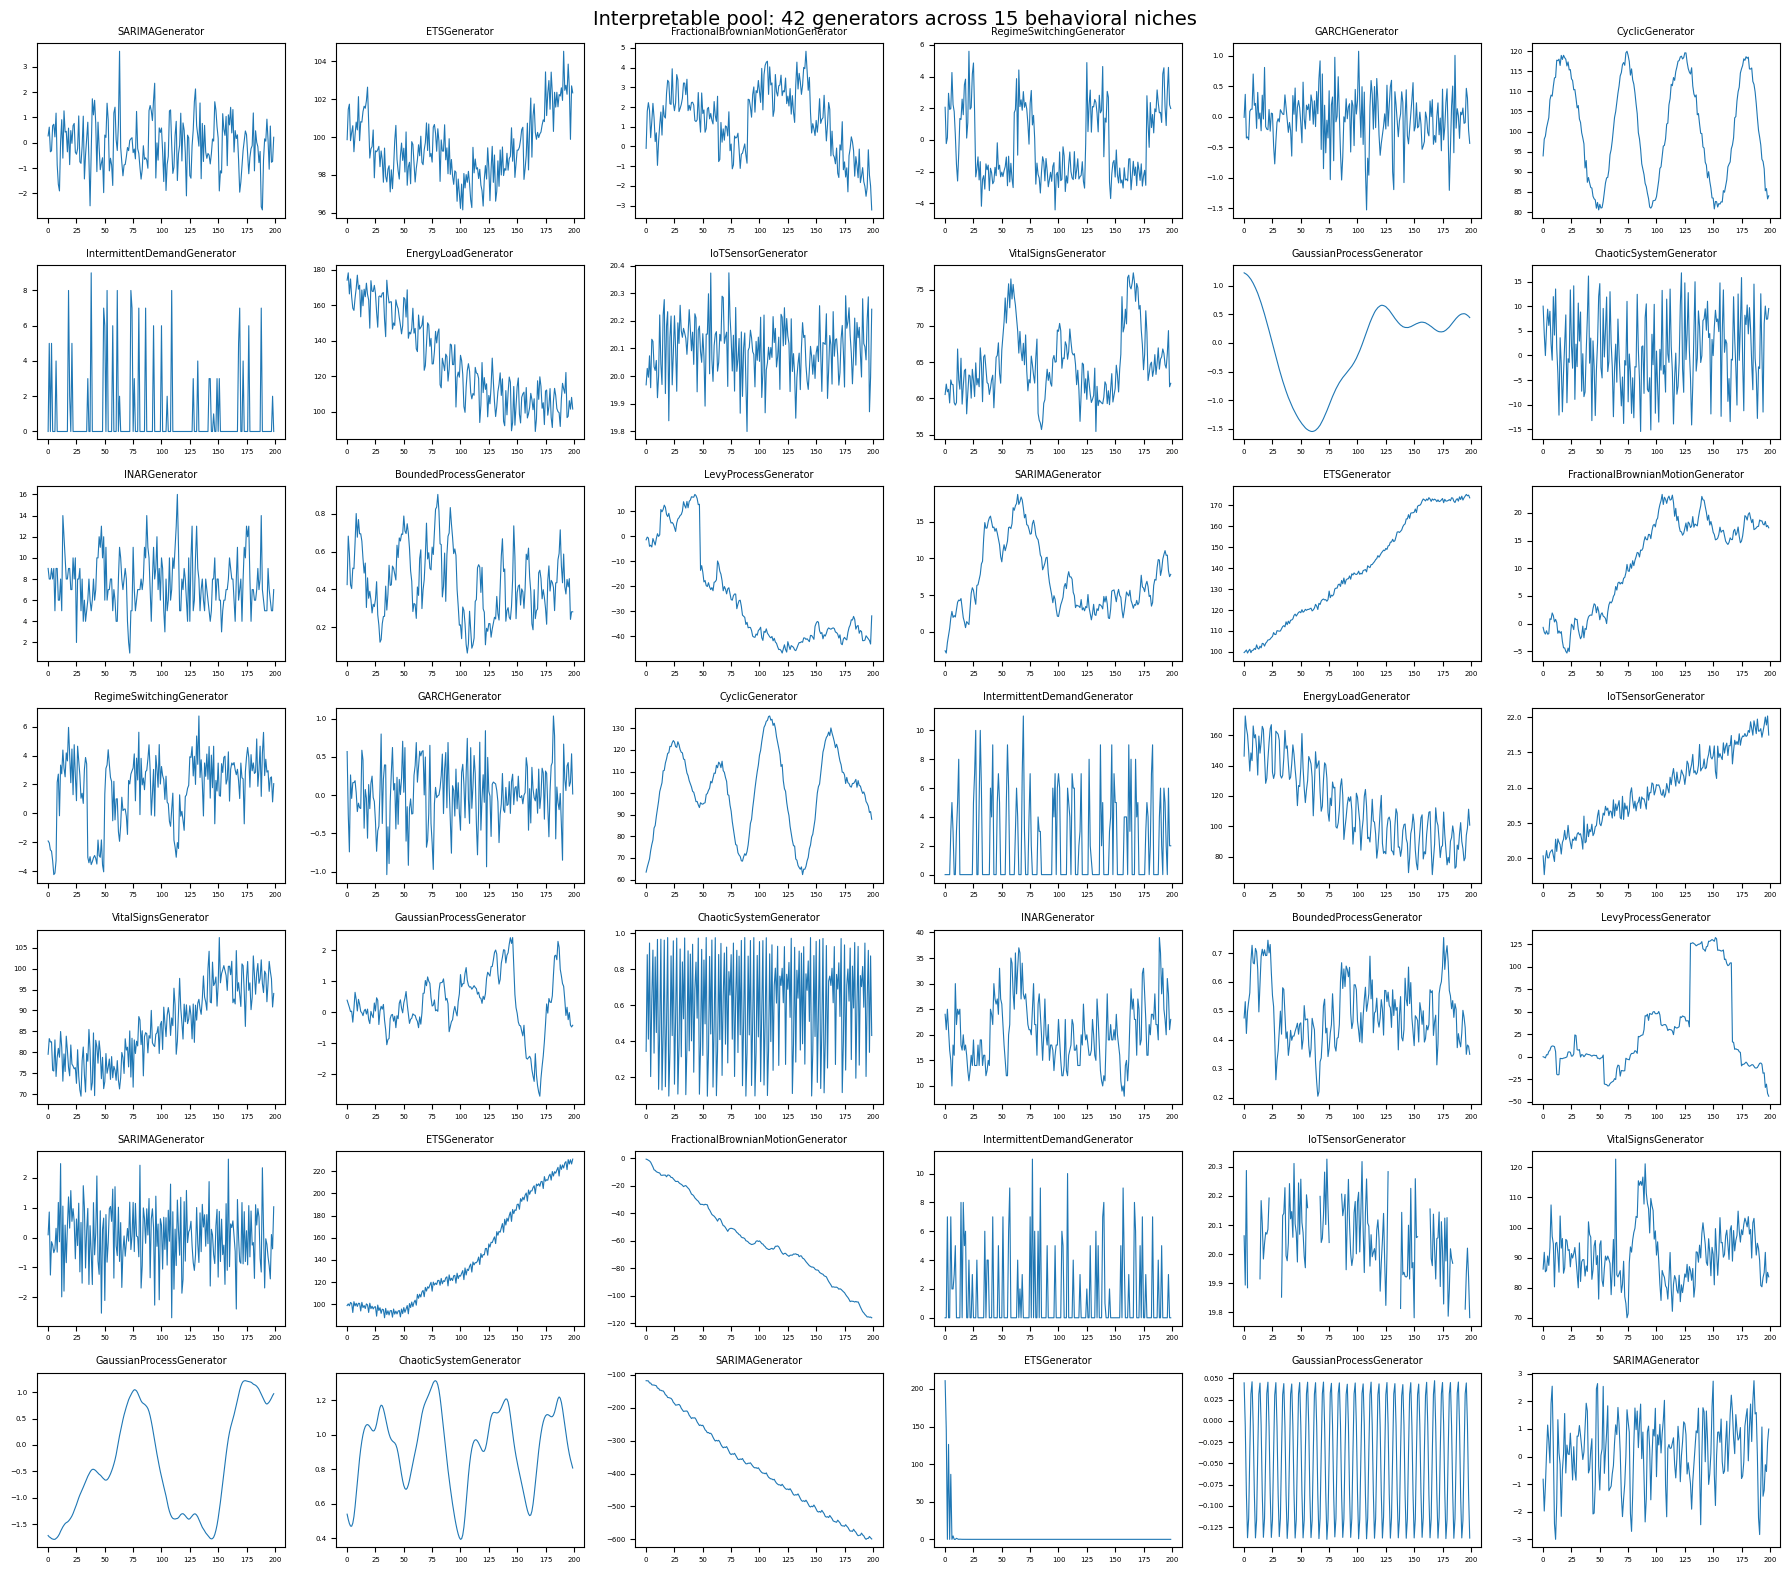
Niche deep-dives
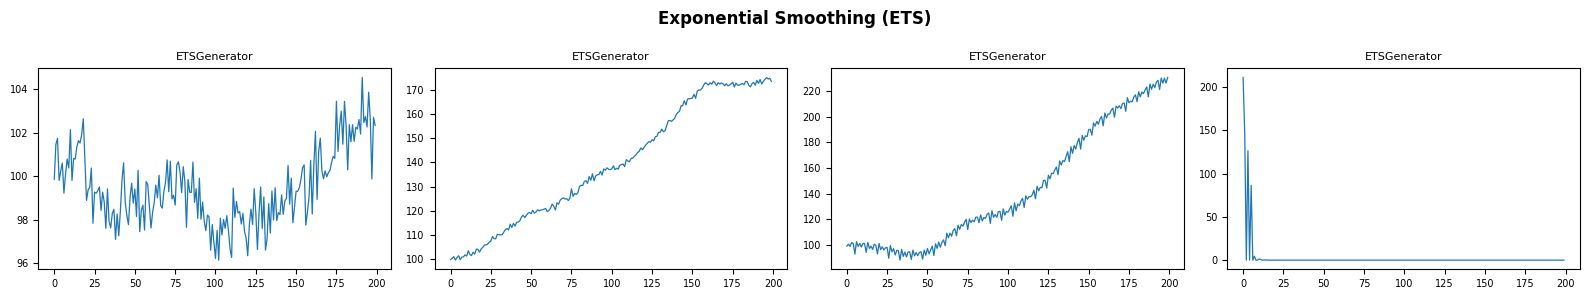
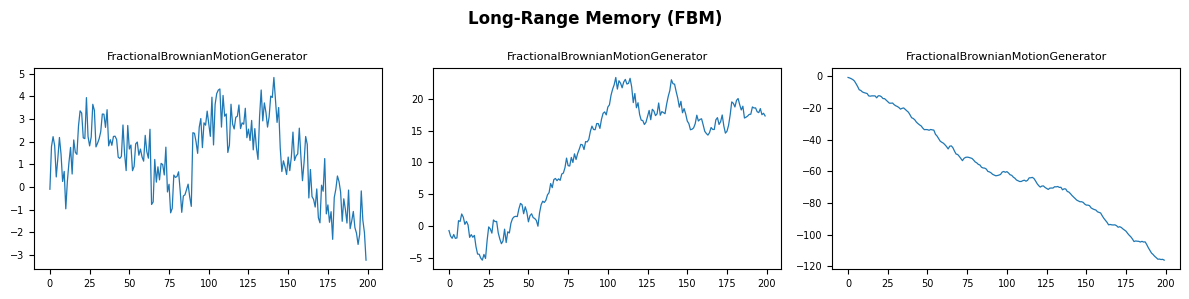
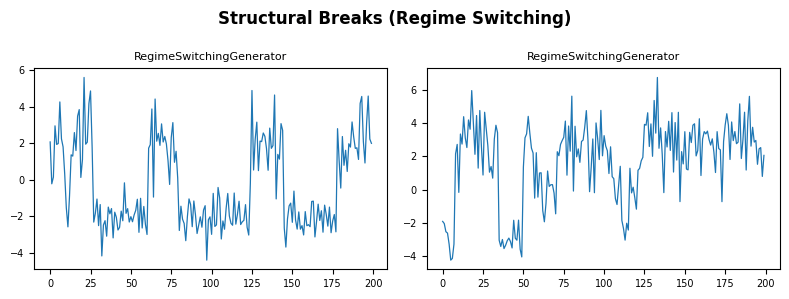
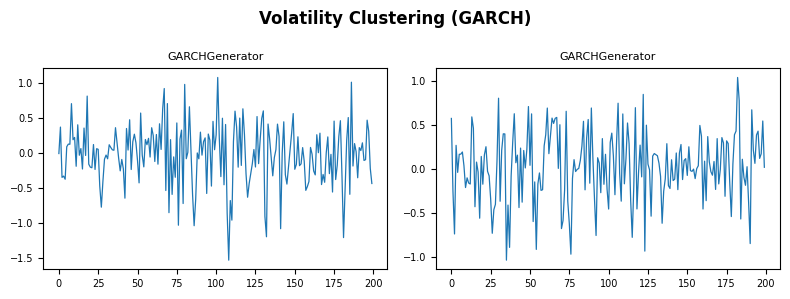
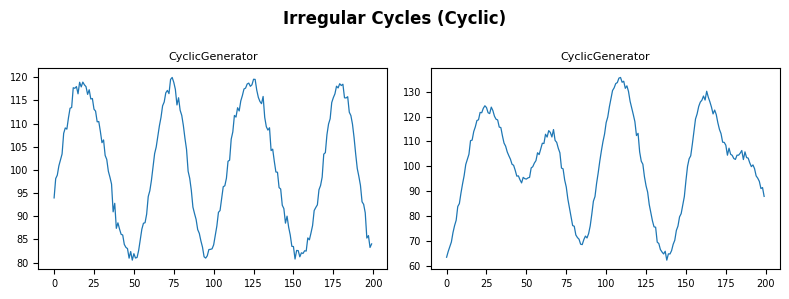
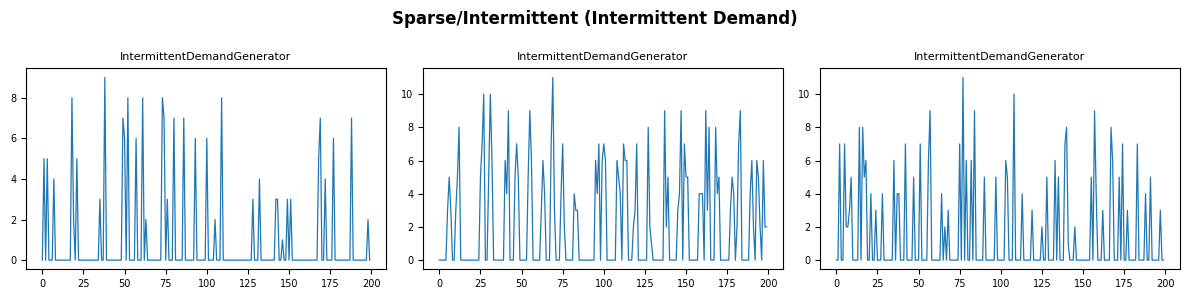
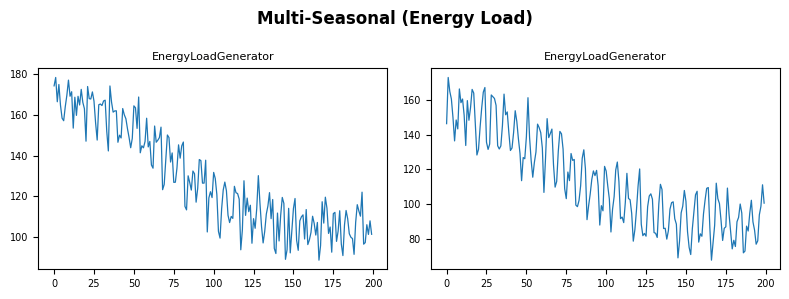
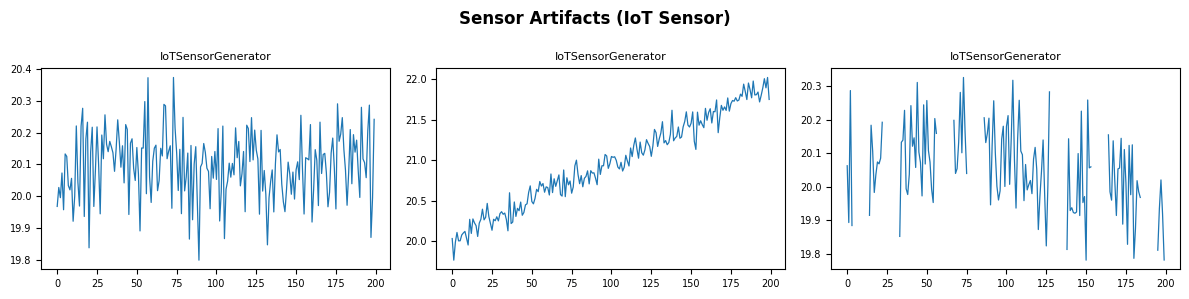
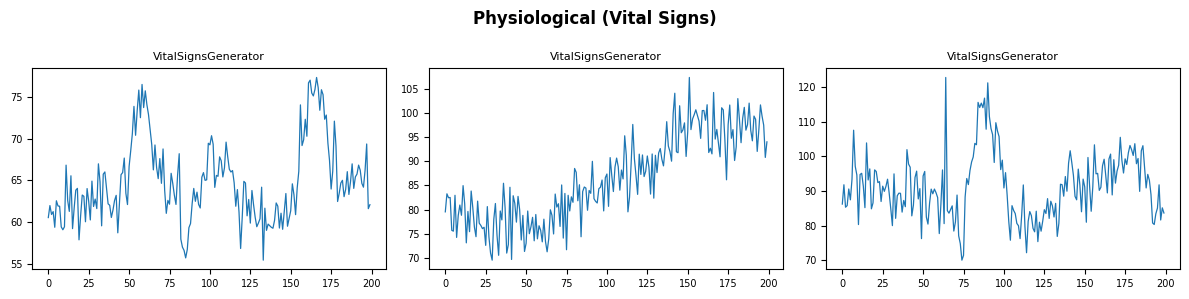
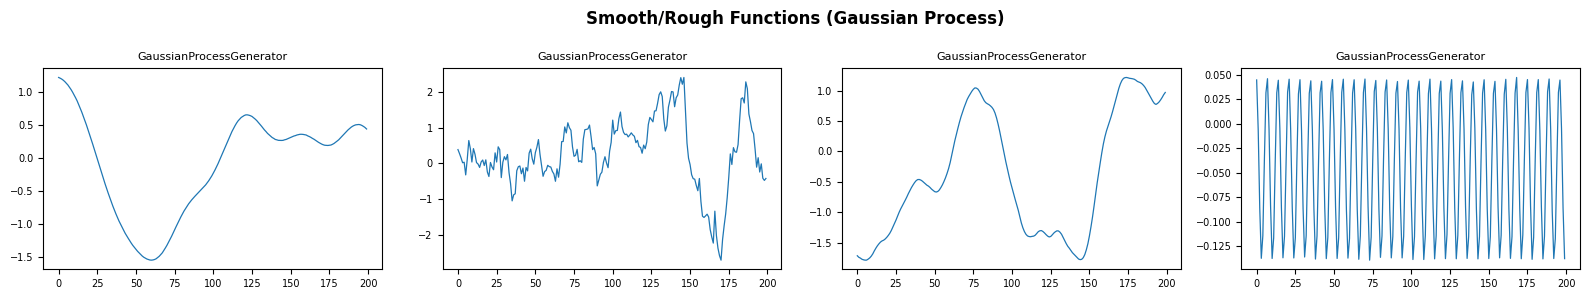
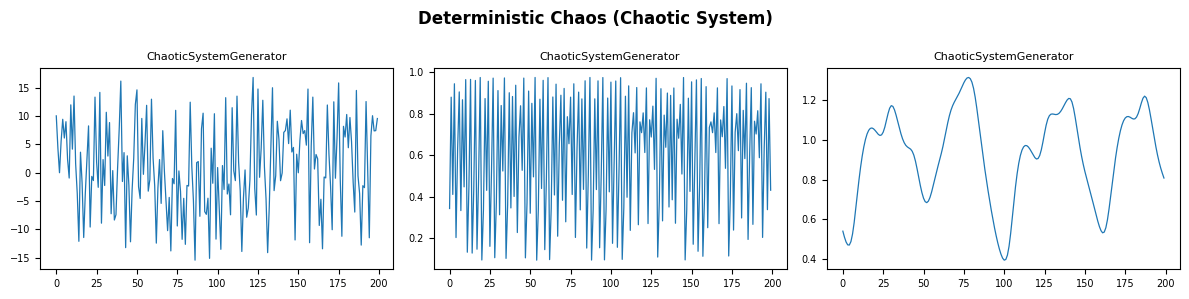
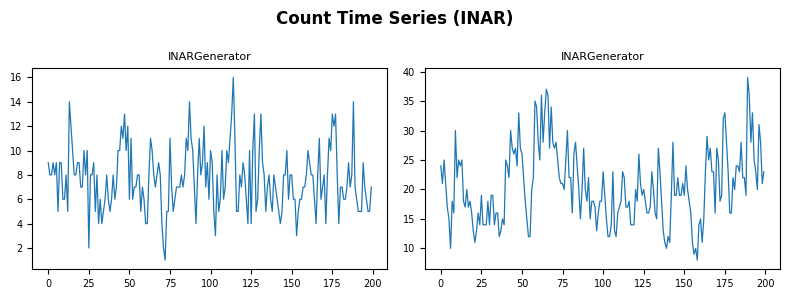
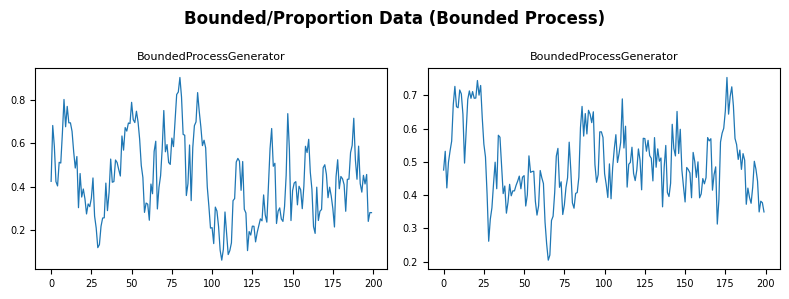
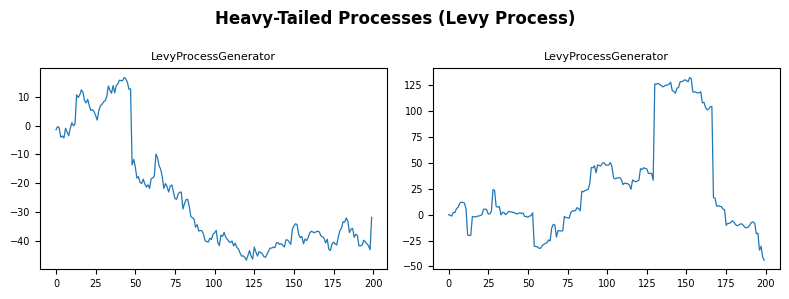
Each behavioral niche contributes a different number of generators. Below we group them by niche and plot the variants side by side.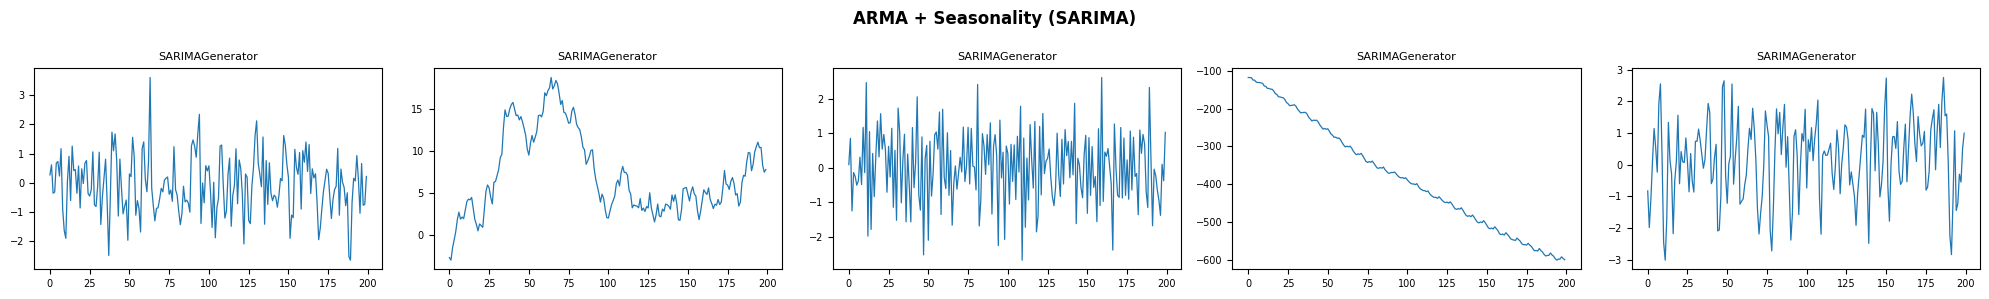
Summary statistics
Compare key statistics across all 42 series to see how the interpretable pool spans different value ranges and variabilities.Scaling up
Generate multiple series per generator for a larger dataset.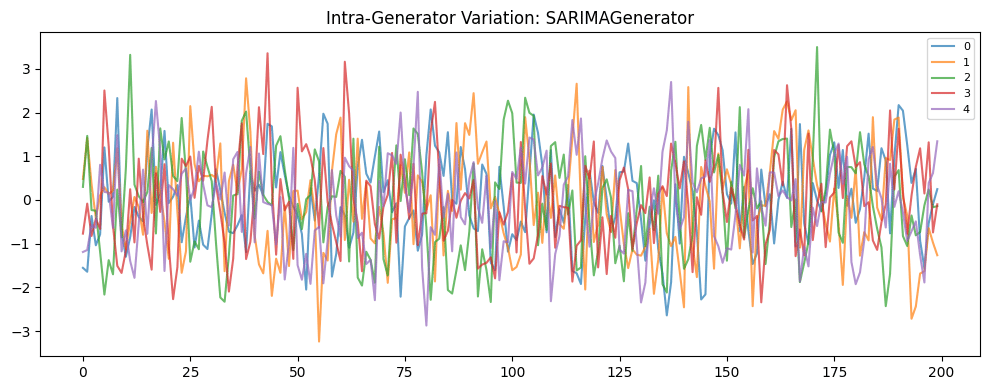
Pretraining pool
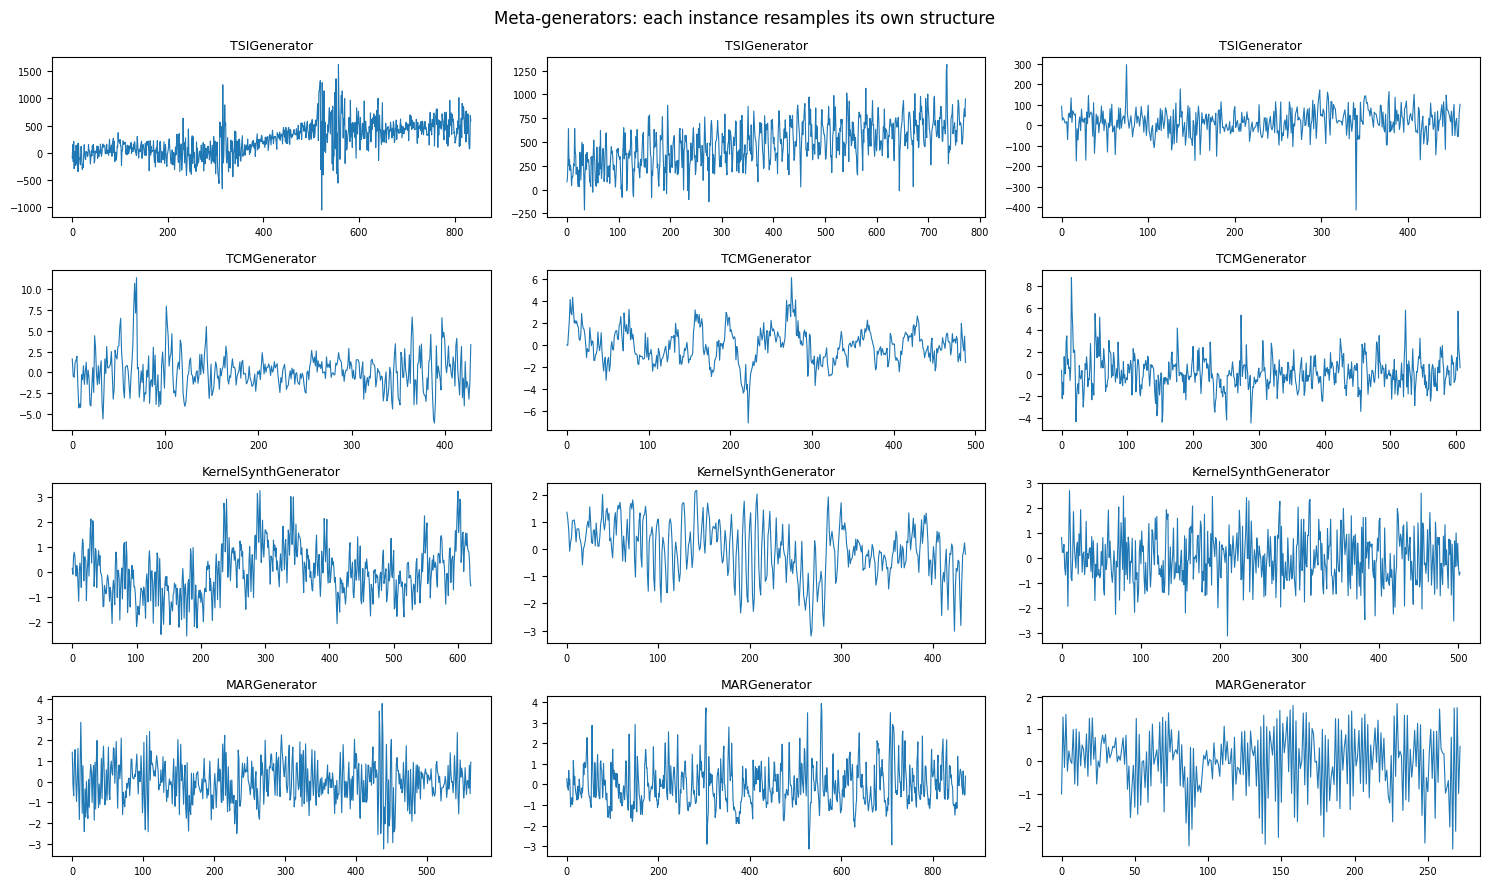
pretraining_pool() is the breadth-maximizing counterpart to
interpretable_pool(). It keeps the 42 single-mechanism instances above
and adds independently-seeded copies of the four meta-generators
interpretable_pool deliberately leaves out — TSIGenerator,
TCMGenerator, KernelSynthGenerator, and MARGenerator. Each of
those resamples a fresh trend/seasonal, causal-graph, GP-kernel, or
mixture-autoregressive configuration per series, so a handful of
instances already spans a very wide distribution — the goal when
pretraining a foundation model rather than benchmarking one named
process. The default length range is wider too (256-1024 steps),
matching typical pretraining contexts.
Two knobs control the mix: n_meta_variants sets how many
independently-seeded copies of each meta-generator to add (default 3),
and include_interpretable=False drops the single-mechanism generators
for a purely procedural corpus.
Seasonal pool
seasonal_pool() is a small, opt-in addition: eight configured
instances of TSIGenerator, ETSGenerator, and SeasonalGenerator
with a pronounced seasonal cycle whose swing moves with the level, under
moderate to heavy noise, persistent dependence, and occasional level or
slope breaks. The period follows freq as elsewhere, so "QS" gives
period 4 and "MS" period 12; yearly frequencies raise because there is
no cycle to build.
Coverage benchmarks on real quarterly and monthly panels found this
region under-represented: real tourism and hospital series had no close
synthetic neighbour in either pool. Adding the seasonal pool on top of
the interpretable pool raised the share of real series with a close
neighbour by 8 to 32 points on tourism, hospital, and M1 monthly panels,
was neutral on M4, and gave nothing on intermittent car-parts data,
where it cost a few points when it displaced the pretraining pool’s
share instead of being added. Its effect on forecasting accuracy has not
been measured, which is why it is not part of any default.